
01 · Shared service levels
Service levels turned stability and performance into measurable expectations for the team.
Customer case study · Consumer internet
Nearbuy wanted to move from reactive incident handling to a preventive reliability and cost program. BluePi established service levels, monitored critical AWS resources, optimized services and Spot capacity, and automated recurring defect detection and resolution.
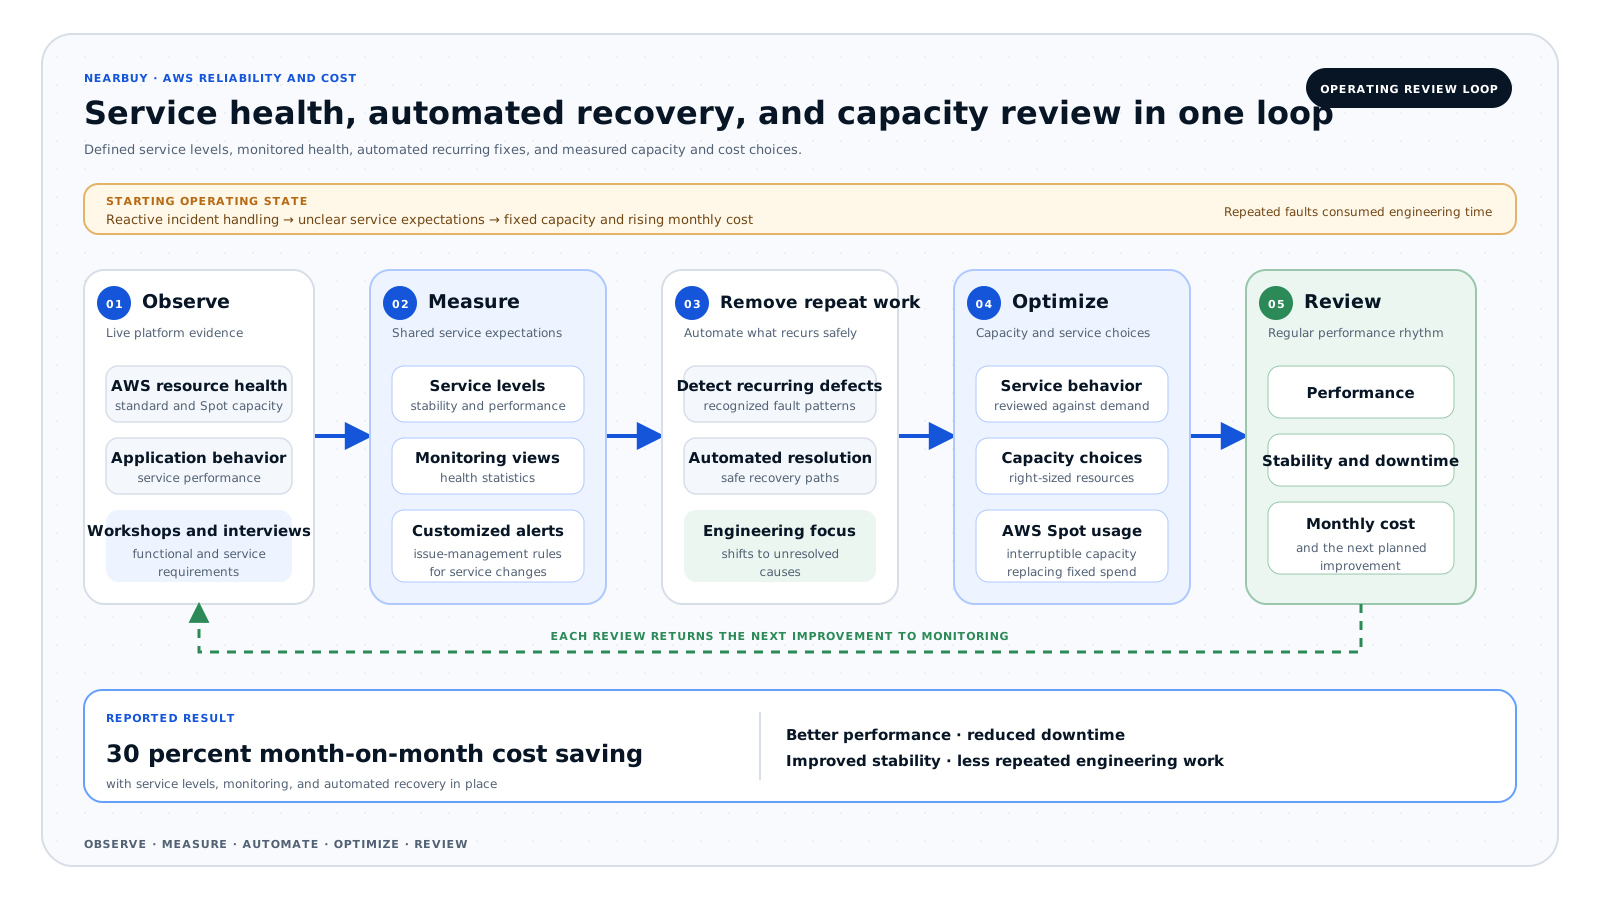
Nearbuy needed to reduce recurring incidents and cloud cost without weakening the live service. BluePi used workshops and stakeholder interviews to define service requirements, then established service levels, monitoring, issue-management practices, recurring-fault automation, and regular performance and cost reviews.
01 · Shared service levels
Service levels turned stability and performance into measurable expectations for the team.
02 · Recurring-fault automation
Automation targeted repeatable detection and recovery patterns so engineers could spend less time on the same issues.
03 · Spot instance savings
AWS Spot instances and service changes contributed to a 30 percent monthly cost saving.
BluePi gathered requirements through workshops and stakeholder interviews, defined service levels, put monitoring and issue management in place, automated recurring fault patterns, and reviewed performance and cost on a regular rhythm. The work improved response, stability, downtime, and monthly cost.
Service levels turned stability and performance into shared operating expectations rather than occasional escalation topics.
Automation targeted repeatable detection and recovery patterns so engineers could focus on unresolved causes.
Resource choices were evaluated against workload and reliability requirements, protecting service while reducing waste.
Where this pattern fits
The same measurement discipline fits any live platform with repeated incidents and unclear unit cost.
Use these questions to judge whether the case fits your operating problem and what a first deployment should prove.
BluePi can begin with a joint review of recent incidents, service measures, workload patterns, and cost allocation. The output identifies immediate operating fixes, recurring work suited to automation, and architecture or capacity changes that need a measured trial.
Direct answers drawn from the case record on this page.
Nearbuy wanted to move from reactive incident handling to a preventive reliability and cost program. BluePi established service levels, monitored critical AWS resources, optimized services and Spot capacity, and automated recurring defect detection and resolution.
Nearbuy needed to reduce recurring incidents and cloud cost without weakening the live service. BluePi used workshops and stakeholder interviews to define service requirements, then established service levels, monitoring, issue-management practices, recurring-fault automation, and regular performance and cost reviews.
The program produced a 30 percent month-on-month cost saving, better performance, lower downtime, stronger stability, and less repeated engineering work. Measured results: 30% lower monthly cloud spend.
Client: NearBuy. Industry: Consumer internet. Platform: AWS.
BluePi can begin with a joint review of recent incidents, service measures, workload patterns, and cost allocation. The output identifies immediate operating fixes, recurring work suited to automation, and architecture or capacity changes that need a measured trial.
Open a section to review the customer problem, implementation, business change, and architecture.
Platform support focused on urgent issues after they caused downtime or productivity loss. The team needed current health data, defined service expectations, preventive alerts, and a repeatable way to remove recurring faults.
BluePi ran functional and non-functional requirement workshops, defined service levels and issue-management processes, monitored critical AWS resources including Spot instances, customized alerts, optimized services and capacity, and automated recurring defect detection and resolution.
The program produced a 30 percent month-on-month cost saving, better performance, lower downtime, stronger stability, and less repeated engineering work.
AWS service and application health entered monitoring and customized alerts. Recurring defects moved through automated detection and resolution where safe, while regular performance and cost reviews identified the next optimization decision.
The platform used microservices, Docker, Kubernetes, Erlang, MongoDB, PostgreSQL, Amazon EMR, and Bamboo. The reliability program monitored the behavior of this estate instead of replacing it with a new technology stack.
The team moved from urgent incident resolution toward defined service measures, preventive alerts, automated handling of recurring faults, and a regular review rhythm for reliability and cost.
Cases that share this industry or platform, for comparison during your evaluation.
Delhivery needed current operating views across a rapidly growing parcel network while keeping historical package and scan data available for analysis. BluePi built an AWS data warehouse and near-real-time reporting path using Amazon S3, Kinesis, Storm, Redis, and Redshift.
Compass Group worked with inconsistent records and conflicting reports across SAP and related systems. BluePi integrated inventory, sales, and operational data on AWS Redshift, established master-data workflows and governance, and applied field-level quality controls.
InfoDrive India’s private-cloud application had manual deployments, limited scaling, and weak operating visibility. BluePi moved the application to AWS, automated delivery, used load testing to right-size capacity, introduced autoscaling, and added application and infrastructure monitoring.