
Platform contract
Define environments, network paths, identity, secrets, encryption, policy, deployment, audit, backup, recovery, regional needs, and the owners of platform code and change.
Requirements to running platform
BluePi designs and builds cloud data platforms around real consumers and workload service levels. The first production slice connects source onboarding, storage, transformation, quality, governance, serving, deployment, observability, recovery, cost, and operating ownership.
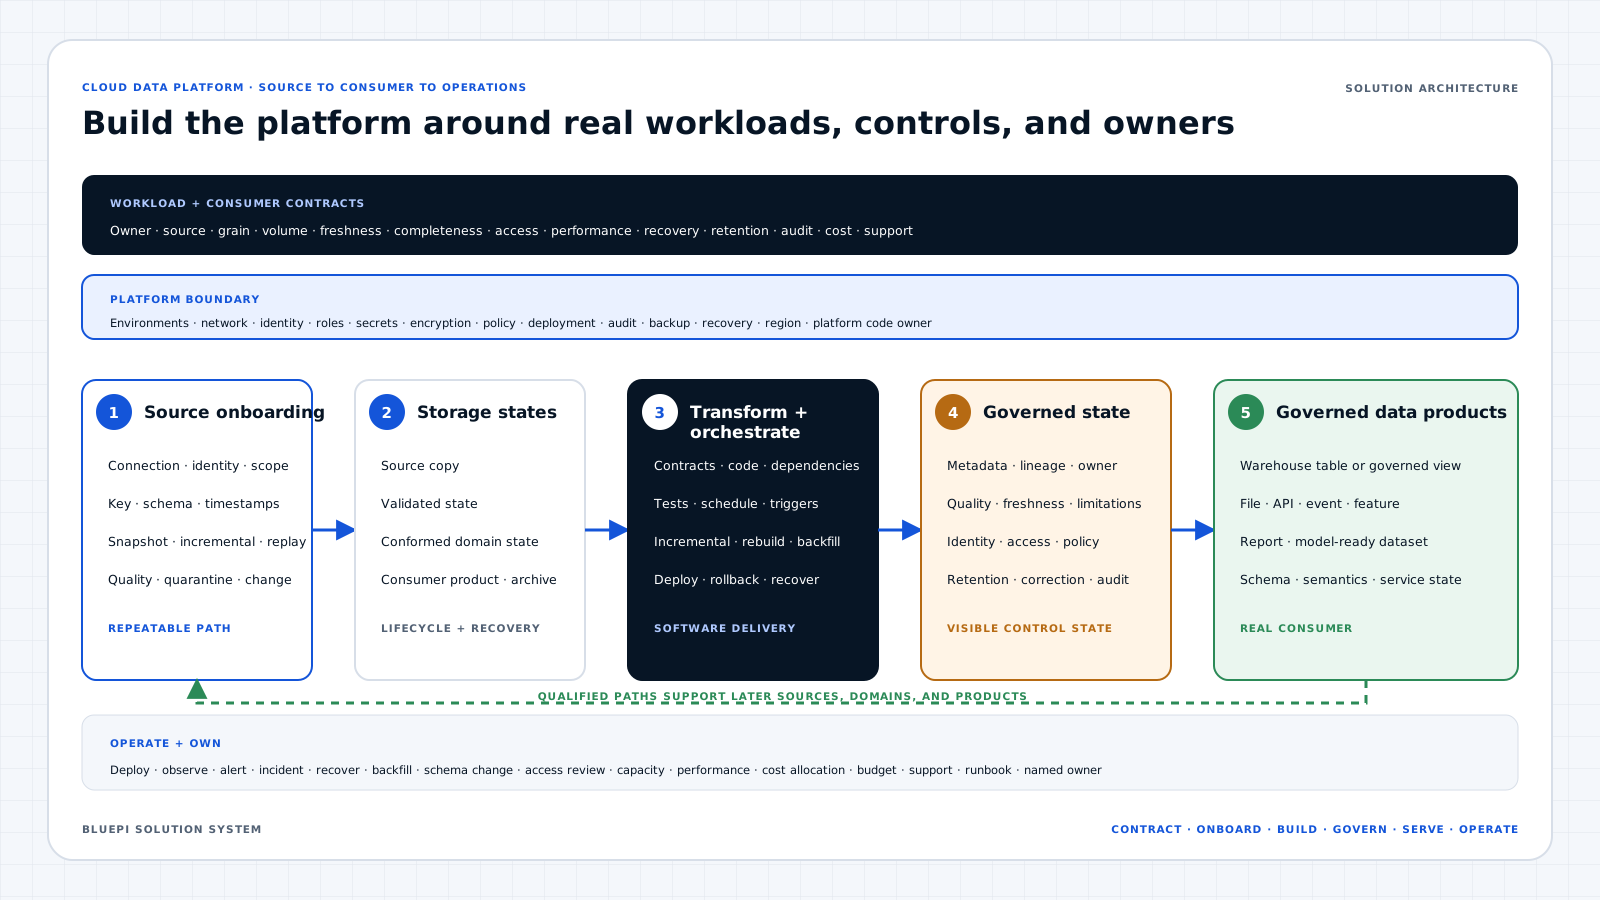
A cloud data platform designed around real consumers
BluePi starts with the workloads and consumers the platform must serve. Their freshness, quality, access, performance, recovery, retention, cost, and support needs set the architecture boundary.
The first production slice proves source onboarding, storage, transformation, governance, serving, deployment, monitoring, recovery, and ownership with real data and a real consumer.
Define environments, network paths, identity, secrets, encryption, policy, deployment, audit, backup, recovery, regional needs, and the owners of platform code and change.
Publish key, grain, schema, semantics, source, lineage, freshness, completeness, quality, access, correction behavior, retention, owner, service expectation, and support.
Exercise deployment, rollback, backfill, schema change, access review, incident response, recovery, performance, capacity, cost review, and support ownership before handover.
When this is the right starting point
Good fit
One use case has someone accountable for the outcome, a baseline the business already measures, and users who can judge whether the result improves.
Poor fit
The request is capacity-only staffing, an unowned demonstration, or a broad transformation without a first decision and finish condition.
What you receive
Open the part you need. Each section expands into the full delivery scope for that step.
Architecture starts with the workloads the platform must support. Each analytical, reporting, operational, migration, or AI workload records its business and technical owners, sources, consumers, data grain, volume, freshness, completeness, query or model behavior, availability, recovery, retention, security, audit, cost, critical windows, and support path.
The platform foundation defines environment separation, account or project structure, network paths, human and service identity, least-privilege roles, secrets, encryption, policy enforcement, deployment, audit, approved connectivity, backup, recovery, and regional requirements. Infrastructure and platform code each have an accountable owner and an environment-promotion path.
Every source receives a contract for ownership, connection, authentication, scope, keys, schema, snapshot and incremental behavior, timestamps, volume, freshness, completeness, deletes, corrections, replay, classification, retention, quality, quarantine, schema change, operations, and cost.
Storage states distinguish source copy, validated data, conformed domain data, consumer-ready products, temporary processing state, and retained archive. Each state defines schema, format, partitioning, ownership, access, promotion criteria, lineage, correction, lifecycle, recovery, performance, and cost.
Transformation code, SQL, notebooks, procedures, and pipelines use repositories, reviews, automated tests, environment promotion, versioned dependencies, and deployment records.
Metadata, quality, lineage, and access follow the data path. Each governed table, view, file, API, event, feature, report, or model-ready dataset publishes its key, grain, schema, semantic definition, source, lineage, freshness, completeness, quality state, access policy, correction behavior, retention, owner, service expectation, and support path.
The first slice includes real sources, transformation logic, one governed product, a real consumer, access controls, quality checks, deployment, monitoring, recovery, cost measurements, and an operating owner. Acceptance covers data and semantic validation, freshness, consumer behavior, performance, security, audit, rollback, failure recovery, capacity, cost, runbooks, and support.
Monitoring separates source, ingestion, storage, transformation, orchestration, quality, serving, security, consumer, and cost layers. Later domains reuse qualified onboarding, transformation, product, quality, access, deployment, observability, recovery, and support paths, with explicit exceptions.
The build includes workload and consumer contracts, environment and security foundations, repeatable source onboarding, storage lifecycle, transformation and orchestration, metadata, quality, lineage, access, governed data products, deployment, monitoring, recovery, cost controls, runbooks, and operating ownership.
The first production slice uses real sources, transformation logic, one governed product, and a real consumer. Acceptance covers data and semantic validation, freshness, performance, access, audit, deployment, rollback, failure recovery, capacity, cost, and support ownership.
Delivery includes Snowflake, Google Cloud, and AWS-based platforms. Product choice follows the workload, consumer, governance, operating, and cost contracts. This solution page does not require one warehouse, lakehouse, cloud provider, or serving technology.
We will look at who owns the decision, the current baseline, the data involved, what the system must include, and the route to go-live.
Review a data-platform constraint